 Stylor
Try Stylor Segment v1
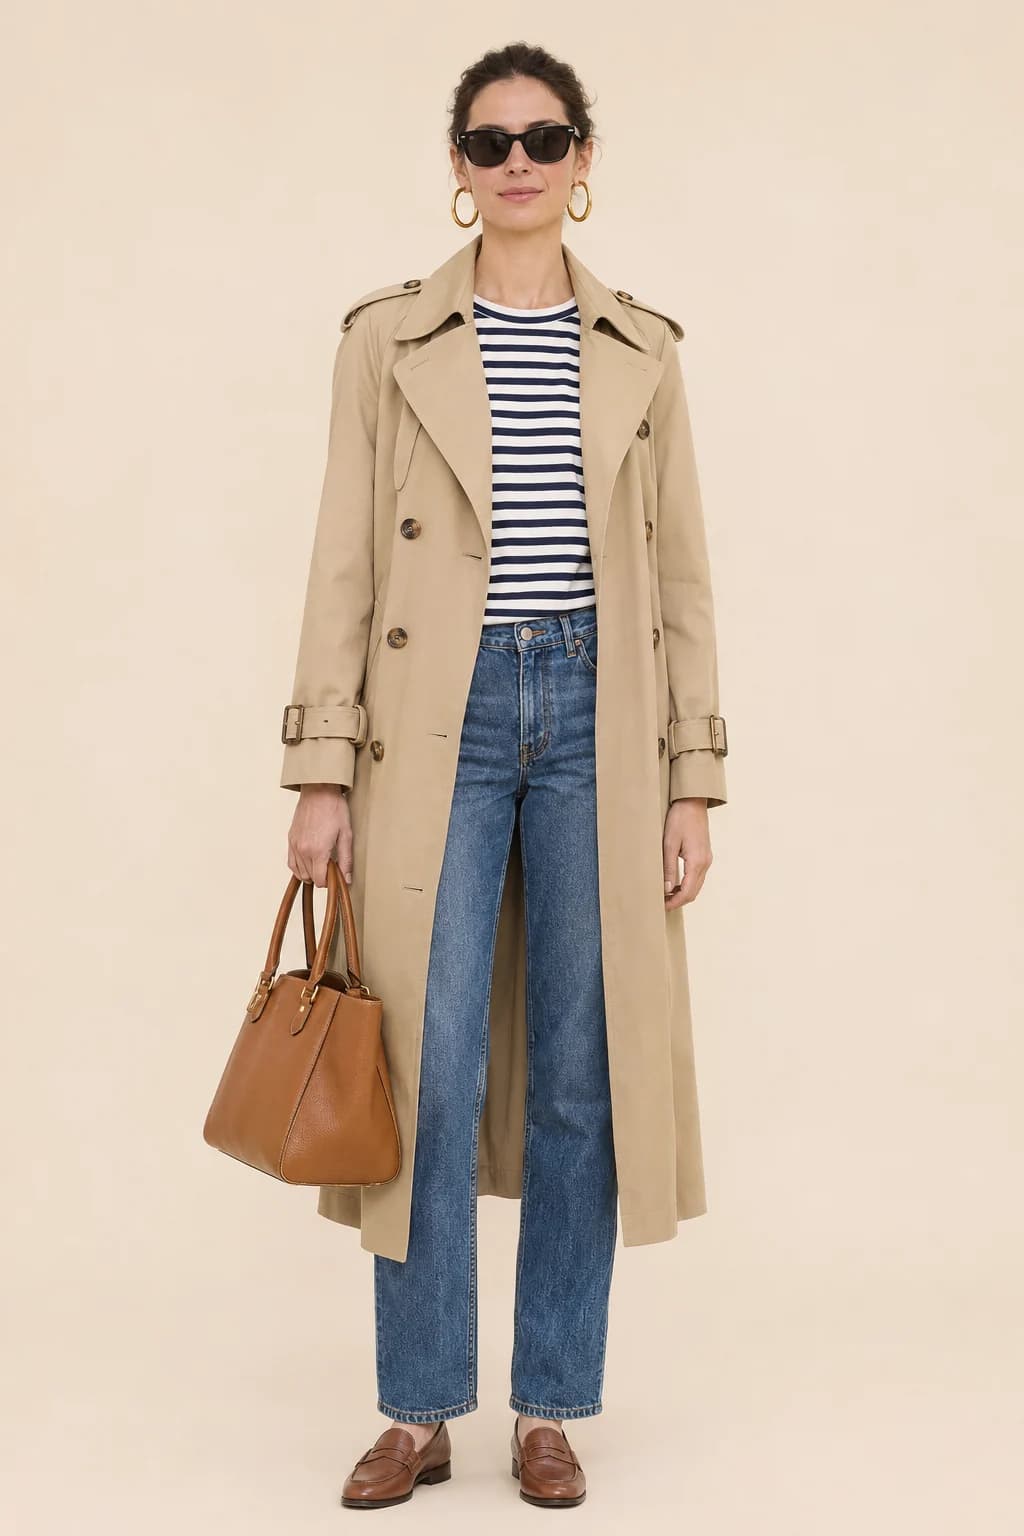
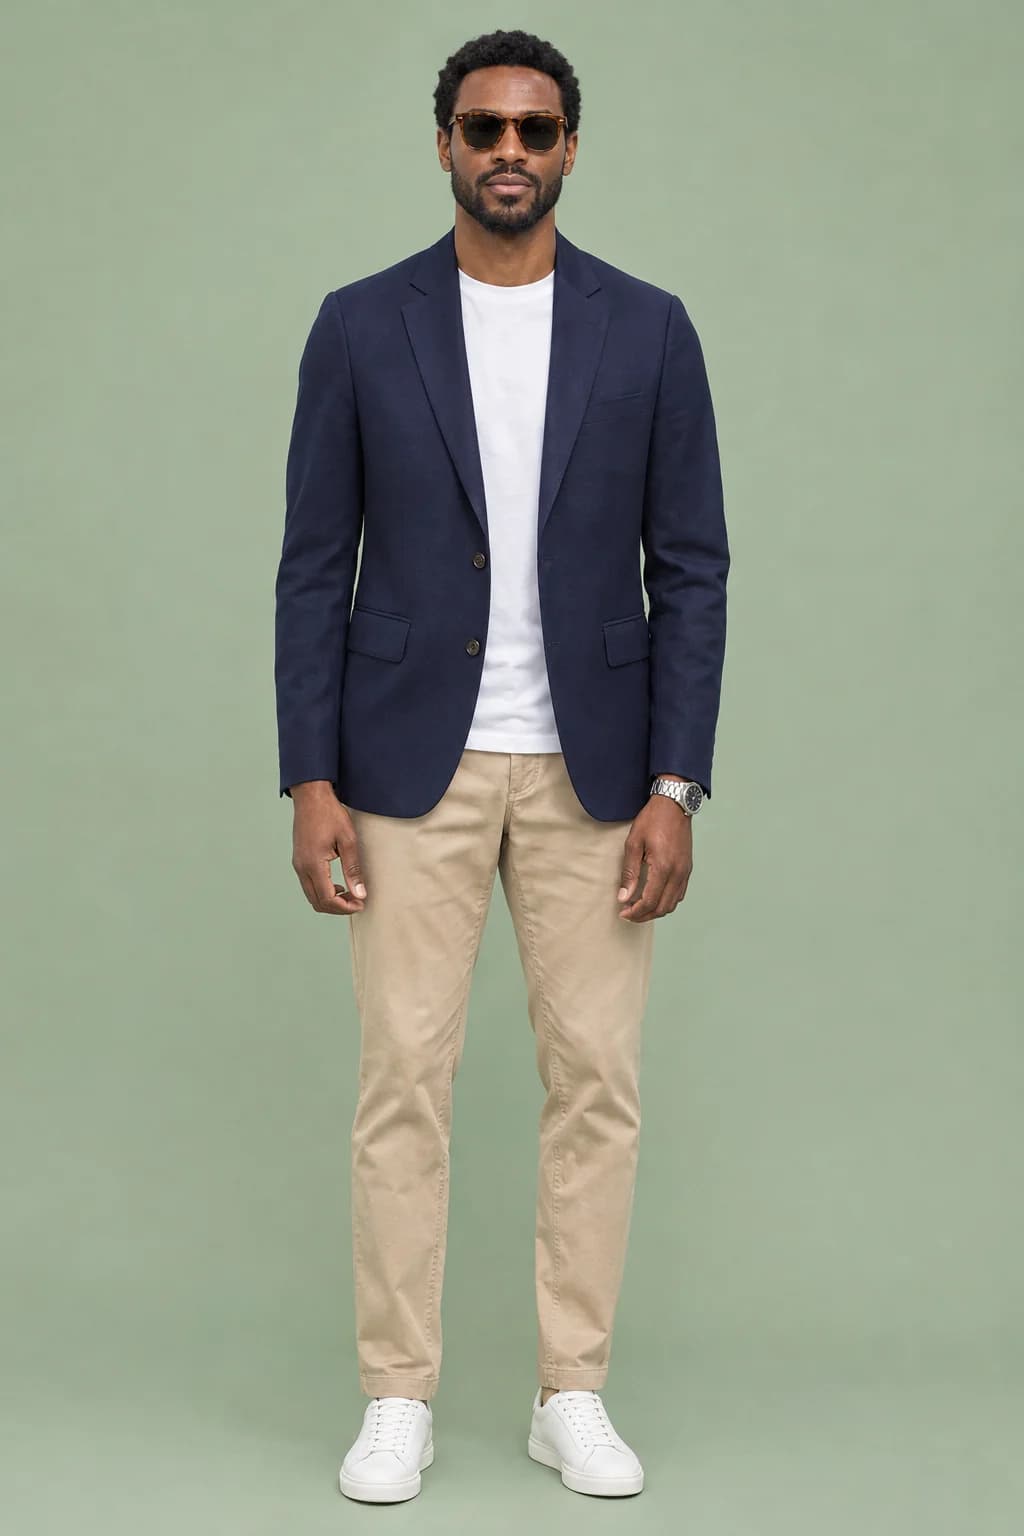
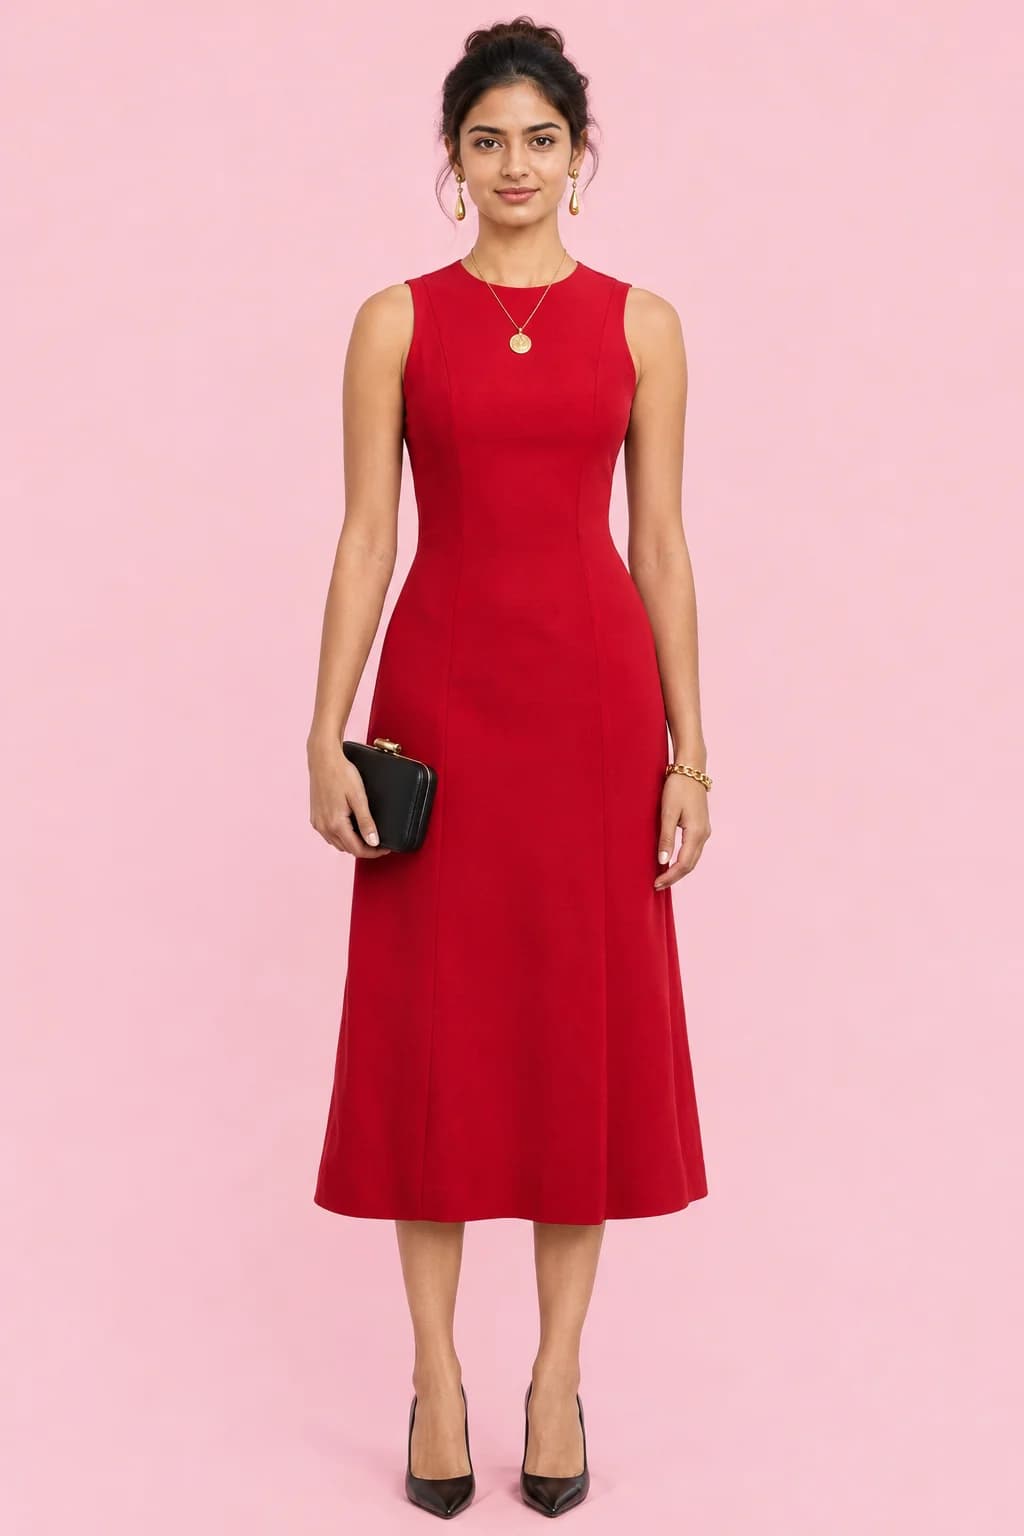
Each photo below is shown with the masks the model returned. Point at a garment to lift it out, or try a photo of your own:
6 items0.19 s
Jewellery and small pieces
Jewellery is small and easy to miss. With zoom on, Segment v1 takes a closer second look at the photo and returns each necklace, ring and earring as its own item:
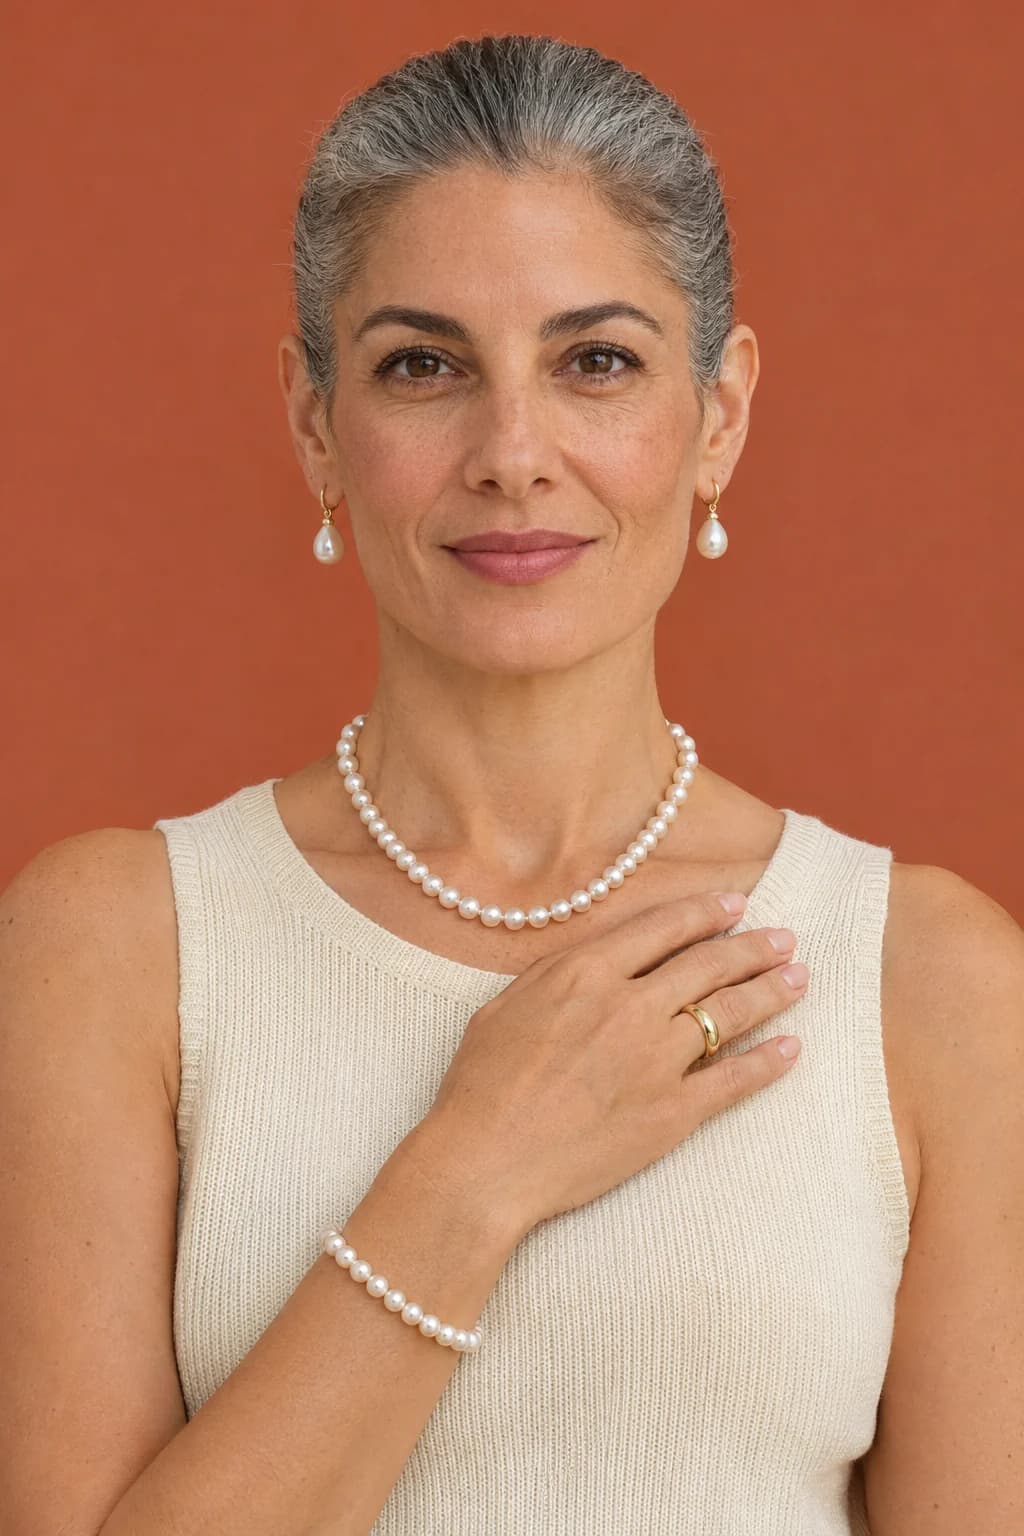
- Necklace
- Bracelet
- Earring
- Ring
Evaluating Stylor Segment v1
We tested Segment v1 against six other open models on four sets of fashion photos, 799 photos in all. On every photo we compared each mask a model returned with one a person drew. The score, item IoU, is how closely the two match, from 0 to 1.
Segment v1 scores highest on all four test sets:
- Stylor Segment v10.795
- Stylor Segment v1, with zoom0.799
- SAM 30.733
- SegFormer-B3 (Fashionpedia)0.643
- Grounded-SAM 20.608
- SegFormer-B2 (clothes)0.570
- FASHN human parser0.521
- YOLOE-11L0.401
SAM 3 comes closest throughout. The lead is not the same everywhere: it is widest on our own benchmark and on Fashionpedia, and narrowest on DeepFashion2.
Speed
Segment v1 is also fast. It takes 0.15 s for a photo, or 0.32 s with zoom. SAM 3, the only model close to it on quality, takes 2.45 s:
Four models are faster than Segment v1. Each of them scores at least 0.15 lower.
Side by side with SAM 3
Four photos where the two models disagree, as each answered them:
Results in full
Item IoU for every model, and the time each took for one photo. The best figure in each column is in bold:
| Model | Average | Time |
|---|---|---|
| Stylor Segment v1 | 0.795 | 0.15 s |
| Stylor Segment v1, with zoom | 0.799 | 0.32 s |
| SAM 3 | 0.733 | 2.45 s |
| SegFormer-B3 (Fashionpedia) | 0.643 | 78 ms |
| Grounded-SAM 2 | 0.608 | 0.29 s |
| SegFormer-B2 (clothes) | 0.570 | 69 ms |
| FASHN human parser | 0.521 | 0.13 s |
| YOLOE-11L | 0.401 | 38 ms |
Methodology
- 1The score. Each hand-drawn item is matched to one of the model’s masks and scored by how much the two overlap. An item the model missed scores 0. A photo’s score is the mean over its items, and a test set’s is the mean over its photos.
- 2The same prompt for every open-vocabulary model. SAM 3, Grounded-SAM 2 and YOLOE were each given the same 38 garment names. Grounded-SAM 2 and YOLOE were run at the detection threshold that scored best for them on a sample of our benchmark.
- 3DeepFashion2’s outlines are loose. They take in hands, phones and hair, so every model scores lower there than its masks deserve.
- 4Time. Every model ran on the same hardware, one photo at a time, timed from the decoded photo to the finished masks.
- 5The test sets. Our benchmark is not public. The other three are: 100 of Fashionpedia’s validation photos, picked for one person in a layered outfit, and 300 each from Clothing Co-Parsing and DeepFashion2. A pair of shoes, socks or gloves counts as one item throughout.
Availability
Stylor Segment v1 is available today on the Stylor API. If you’re a developer, use stylor-segment-v1 on the segment endpoint. The docs have the full reference, every label, and code for using a mask in JavaScript and Python.